Caching with Redis in Node.js
Add Redis caching to your Node.js API — connect with ioredis, implement cache-aside pattern, cache Express routes, set TTLs, invalidate cache on writes, and use Redis for rate limiting and session storage.
Caching with Redis in Node.js
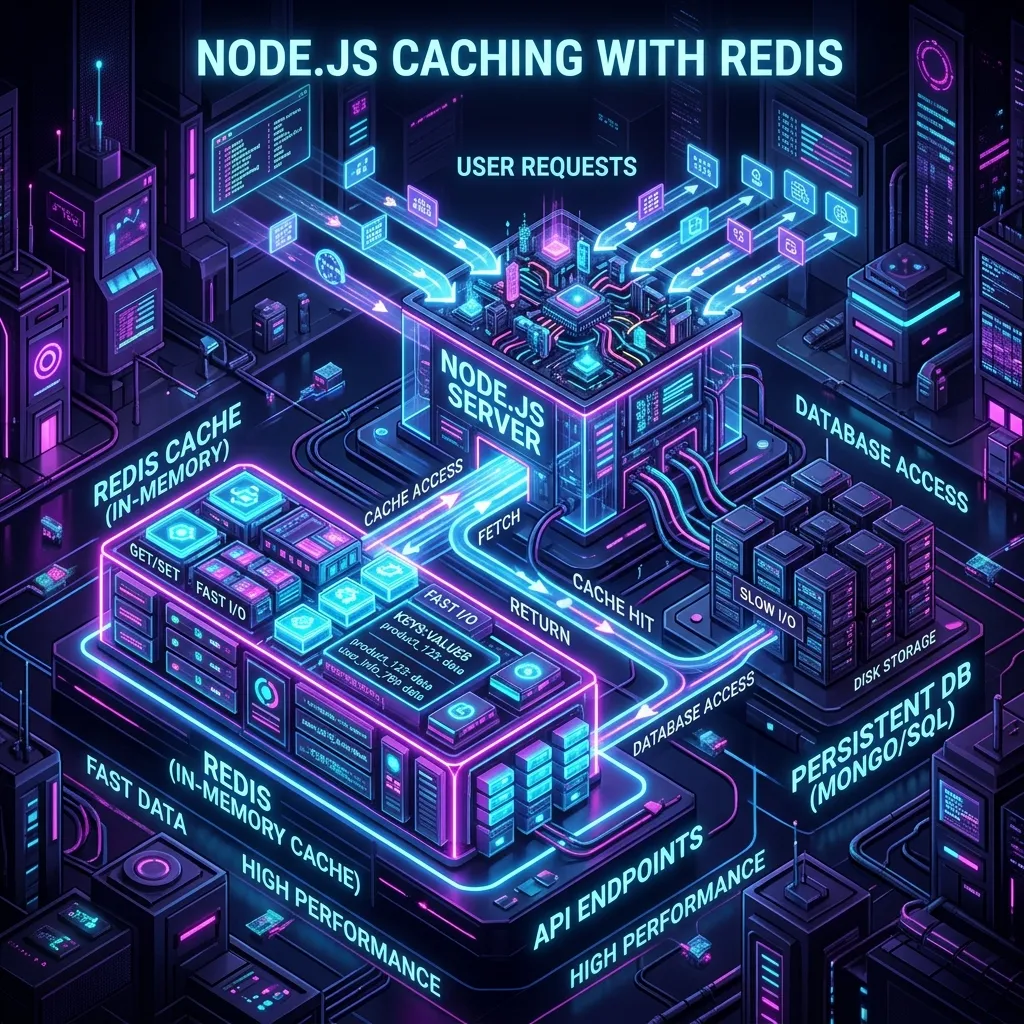
A database query that takes 50ms is fast. Run it 10,000 times per minute and you have a problem. Redis solves this by sitting between your application and the database — storing the results of expensive operations in memory so subsequent requests get the answer in under a millisecond.
Caching is not a band-aid for slow queries. It is a deliberate architectural layer that every production API eventually needs. This module covers everything from connecting to Redis, to implementing cache-aside, to invalidating stale data cleanly.
This is Module 17 of the Node.js Full‑Stack Developer course.
Running Redis Locally
# docker-compose.yml
services:
  redis:
    image: redis:7-alpine
    ports:
      - "6379:6379"
    volumes:
      - redis_data:/data
    command: redis-server --appendonly yes   # persist to disk

volumes:
redis_data:docker compose up -d redis
# Verify it's running
docker exec -it <container_id> redis-cli ping
# PONGInstalling ioredis
npm install ioredisSingleton Redis Client
// lib/redis.js
import Redis from 'ioredis';

const redis = new Redis({
  host: process.env.REDIS_HOST ?? 'localhost',
  port: parseInt(process.env.REDIS_PORT ?? '6379'),
  password: process.env.REDIS_PASSWORD,
  maxRetriesPerRequest: 3,
  lazyConnect: true,            // don't connect until first command
  enableOfflineQueue: false,    // fail fast if Redis is down
});

redis.on('connect', () => console.log('Redis connected'));
redis.on('error', (err) => console.error('Redis error:', err.message));

export default redis;# .env
REDIS_HOST=localhost
REDIS_PORT=6379
REDIS_PASSWORD= # empty for local devThe Cache-Aside Pattern
This is the foundation of almost every caching implementation:
Request
   │
   ▼
Check cache ──hit──▶ Return cached data
   │
  miss
   │
   ▼
Query database
   │
   ▼
Store in cache (with TTL)
   │
   ▼
Return data
Implementation
// lib/cache.js
import redis from './redis.js';

const DEFAULT_TTL = 60; // seconds

/**
 * Get from cache or compute and store the result.
 * @param {string} key   - Cache key
 * @param {Function} fn  - Async function that returns the value on cache miss
 * @param {number} ttl   - Seconds to cache the result
 */
export async function getOrSet(key, fn, ttl = DEFAULT_TTL) {
  // 1. Try the cache
  const cached = await redis.get(key);
  if (cached !== null) {
    return JSON.parse(cached);
  }

  // 2. Cache miss — compute the value
  const value = await fn();

  // 3. Store in cache (fire-and-forget, don't block the response)
  redis.set(key, JSON.stringify(value), 'EX', ttl).catch(err => {
    console.error('Cache write error:', err.message);
  });

  return value;
}

/**
 * Invalidate one or more cache keys.
 */
export async function invalidate(...keys) {
  if (keys.length === 0) return;
  await redis.del(...keys);
}

/**
 * Invalidate all keys matching a pattern (e.g. 'posts:list:*').
 * Uses SCAN to avoid blocking Redis with KEYS command.
 */
export async function invalidatePattern(pattern) {
  const stream = redis.scanStream({ match: pattern, count: 100 });
  const pipeline = redis.pipeline();
  let count = 0;

  stream.on('data', (keys) => {
    for (const key of keys) {
      pipeline.del(key);
      count++;
    }
  });

  await new Promise((resolve, reject) => {
    stream.on('end', resolve);
    stream.on('error', reject);
  });

  if (count > 0) await pipeline.exec();
}
Caching a Service Layer
Apply caching inside the service, not the controller or router. The HTTP layer should not know or care about caching.
// features/posts/posts.service.js
import { prisma } from '../../lib/prisma.js';
import { getOrSet, invalidate, invalidatePattern } from '../../lib/cache.js';

const CACHE_TTL = {
  list: 60,         // 60 seconds for lists
  single: 300,      // 5 minutes for individual records
};

export async function listPosts({ page = 1, limit = 20 } = {}) {
  const cacheKey = `posts:list:page=${page}:limit=${limit}`;

  return getOrSet(cacheKey, async () => {
    const skip = (page - 1) * limit;
    const [posts, total] = await Promise.all([
      prisma.post.findMany({
        where: { published: true },
        orderBy: { createdAt: 'desc' },
        skip,
        take: limit,
        include: { author: { select: { id: true, name: true } }, tags: true },
      }),
      prisma.post.count({ where: { published: true } }),
    ]);
    return { data: posts, meta: { total, page, limit } };
  }, CACHE_TTL.list);
}

export async function getPostById(id) {
  const cacheKey = `posts:single:${id}`;

  return getOrSet(cacheKey, async () => {
    const post = await prisma.post.findUnique({
      where: { id },
      include: {
        author: { select: { id: true, name: true } },
        tags: true,
      },
    });
    if (!post) {
      const { AppError } = await import('../../lib/errors.js');
      throw new AppError('Post not found', 404);
    }
    return post;
  }, CACHE_TTL.single);
}

export async function createPost(data) {
  const post = await prisma.post.create({ data });

  // Invalidate all list caches — new post affects every page
  await invalidatePattern('posts:list:*');

  return post;
}

export async function updatePost(id, data) {
  const post = await prisma.post.update({ where: { id }, data });

  // Invalidate the specific post and all lists
  await Promise.all([
    invalidate(`posts:single:${id}`),
    invalidatePattern('posts:list:*'),
  ]);

  return post;
}

export async function deletePost(id) {
  await prisma.post.delete({ where: { id } });

  await Promise.all([
    invalidate(`posts:single:${id}`),
    invalidatePattern('posts:list:*'),
  ]);
}
Cache Key Design
Good cache keys are deterministic, unique, and scoped:
posts:list:page=1:limit=20
posts:list:page=2:limit=20:authorId=abc123
posts:single:abc123
users:single:def456
users:list:role=admin:page=1
search:q=nodejs&page=1
Rules:
- Use
:as separator — it is conventional in Redis - Include every parameter that affects the result
- Prefix by resource type so you can invalidate by pattern (
posts:*) - Never cache user-specific data under a shared key (prefix with
userId)
// User-specific cache keys
const cacheKey = `users:${userId}:orders:page=${page}`;
Express Middleware Cache
For simple, coarse-grained caching on public routes, a middleware is convenient:
// middleware/cache.js
import redis from '../lib/redis.js';

/**
 * Cache the full HTTP response for GET requests.
 * @param {number} ttl - seconds
 */
export function httpCache(ttl = 60) {
  return async (req, res, next) => {
    // Only cache GET requests
    if (req.method !== 'GET') return next();

    const key = `http:${req.originalUrl}`;

    try {
      const cached = await redis.get(key);
      if (cached) {
        res.setHeader('X-Cache', 'HIT');
        res.setHeader('Content-Type', 'application/json');
        return res.send(cached);
      }
    } catch (err) {
      // Redis unavailable — serve uncached
      console.error('Cache read error:', err.message);
      return next();
    }

    // Intercept res.json to store the response in cache
    const originalJson = res.json.bind(res);
    res.json = (body) => {
      redis
        .set(key, JSON.stringify(body), 'EX', ttl)
        .catch(err => console.error('Cache write error:', err.message));
      res.setHeader('X-Cache', 'MISS');
      return originalJson(body);
    };

    next();
  };
}// posts.router.js
import { httpCache } from '../../middleware/cache.js';
router.get('/', httpCache(60), controller.list);
router.get('/:id', httpCache(300), controller.getById);Rate Limiting with Redis
Redis is the ideal backend for distributed rate limiting because it is shared across all instances of your API:
npm install express-rate-limit rate-limit-redis// middleware/rateLimiter.js
import rateLimit from 'express-rate-limit';
import { RedisStore } from 'rate-limit-redis';
import redis from '../lib/redis.js';
export const apiLimiter = rateLimit({
windowMs: 15 * 60 * 1000, // 15 minutes
max: 100, // 100 requests per window per IP
standardHeaders: true,
legacyHeaders: false,
store: new RedisStore({
sendCommand: (...args) => redis.call(...args),
}),
message: { status: 'error', message: 'Too many requests, please try again later.' },
});
export const authLimiter = rateLimit({
windowMs: 15 * 60 * 1000,
max: 10, // stricter limit for login/register
store: new RedisStore({
sendCommand: (...args) => redis.call(...args),
prefix: 'rl:auth:',
}),
message: { status: 'error', message: 'Too many login attempts.' },
});// app.js
import { apiLimiter, authLimiter } from './middleware/rateLimiter.js';
app.use('/api/', apiLimiter);
app.use('/api/v1/auth', authLimiter);Session Storage with Redis
For session-based authentication (alternative to JWT), Redis stores sessions server-side:
npm install express-session connect-redis// app.js
import session from 'express-session';
import RedisStore from 'connect-redis';
import redis from './lib/redis.js';
app.use(
session({
store: new RedisStore({ client: redis }),
secret: process.env.SESSION_SECRET,
resave: false,
saveUninitialized: false,
cookie: {
httpOnly: true,
secure: process.env.NODE_ENV === 'production',
maxAge: 7 * 24 * 60 * 60 * 1000, // 7 days
sameSite: 'lax',
},
})
);Sessions are stored as sess:<sessionId> keys in Redis and expire automatically when maxAge is reached.
Useful Redis Commands for Debugging
# Connect to Redis CLI
redis-cli

# List all keys (dev only — never in production with large datasets)
KEYS *

# List keys by pattern safely
SCAN 0 MATCH posts:* COUNT 100

# Get a value
GET posts:single:abc123

# Check TTL remaining (seconds)
TTL posts:single:abc123

# Delete a key
DEL posts:single:abc123

# Delete all keys matching pattern
SCAN 0 MATCH posts:list:* COUNT 100
# then DEL each key returned

# Monitor all commands in real time (dev only)
MONITOR

# Check memory usage
INFO memory

# Flush all keys (dev only — DANGEROUS)
FLUSHALL
Handling Redis Unavailability
Redis should be treated as an optional performance layer — if it goes down, the application must continue to function (just slower):
// lib/cache.js — resilient version
export async function getOrSet(key, fn, ttl = DEFAULT_TTL) {
  try {
    const cached = await redis.get(key);
    if (cached !== null) return JSON.parse(cached);
  } catch (err) {
    // Redis unavailable — skip the cache, go to database
    console.error(`Cache get failed for key "${key}":`, err.message);
    return fn();
  }

  const value = await fn();

  try {
    await redis.set(key, JSON.stringify(value), 'EX', ttl);
  } catch (err) {
    console.error(`Cache set failed for key "${key}":`, err.message);
  }

  return value;
}
In production, use Redis Sentinel or Redis Cluster for high availability. On cloud platforms, managed services like Upstash, Redis Cloud, or AWS ElastiCache handle this for you.
Environment Variables
# .env
REDIS_HOST=localhost
REDIS_PORT=6379
REDIS_PASSWORD=your_redis_password   # required in production
REDIS_TLS=true                        # required for cloud Redis
For TLS-enabled cloud Redis:
const redis = new Redis({
  host: process.env.REDIS_HOST,
  port: parseInt(process.env.REDIS_PORT),
  password: process.env.REDIS_PASSWORD,
  tls: process.env.REDIS_TLS === 'true' ? {} : undefined,
});
Node.js Full‑Stack Course — Module 17 of 32
Your API now serves cached responses in under a millisecond. Continue to Module 18 to secure your API with JWT authentication.
Summary
Redis caching transforms a database-bound API into a high-throughput service:
- Run Redis locally with Docker; use a managed service (Upstash, ElastiCache) in production
- Export a single
ioredisclient instance fromlib/redis.js— never create one per request - The cache-aside pattern: check cache → miss → query DB → store in cache → return
- Apply caching in the service layer, not the controller or router
- Design cache keys to include every parameter that affects the result; use prefixes for pattern-based invalidation
- Invalidate on writes: delete the specific key and any affected list keys immediately after a mutation
- Use
SCANnotKEYSfor pattern-based invalidation in production - Redis also powers rate limiting (with
express-rate-limit+rate-limit-redis) and session storage - Always handle Redis failures gracefully — fall through to the database rather than crashing the request
Continue to Module 18: JWT Authentication →